∎/Proof
Every run, so you can check it yourself.
The tests behind our homepage, in full: what each tool was given, the setting it ran at, and what it answered. The page is rebuilt whenever a new run is published.
Updated 18 October 2026
01/Consistency
Re-test, October 2026
The same input and the same request, run many times on each tool. A tool you can rely on gives the same answer every run. Runs made 17 October 2026 – 18 October 2026.
Spectrum analysis
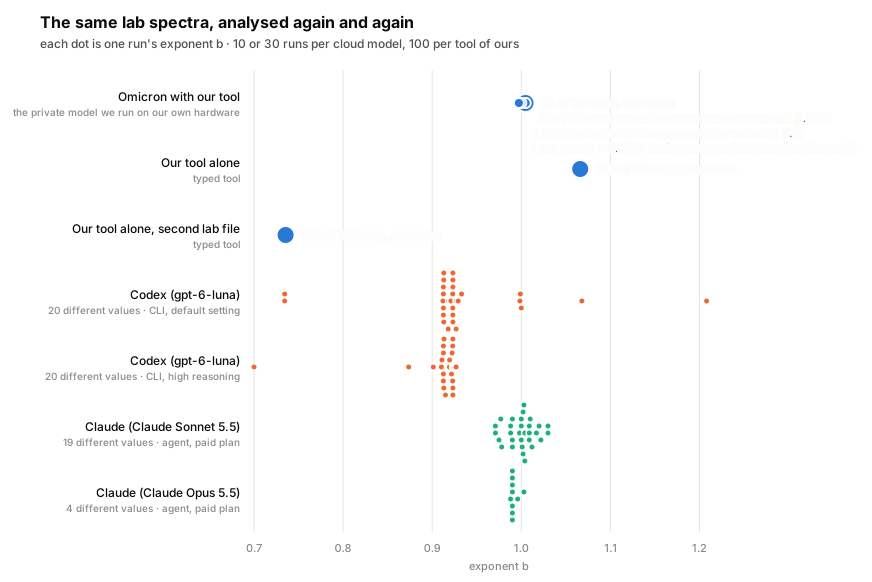
Measured: the power-law exponent b of a set of lab spectra; the tool reads the lab file, the outside models read a labelled export of the same numbers. Input: available on request (its owner has not cleared it for publishing).
| Tool | Runs | Usable | Same answer | Different answers | What happened |
|---|---|---|---|---|---|
| Our tool alonetyped tool, fresh upload each run, no language model in the loop | 100 | 100 | 100 of 100 | 1 | The same result every time (the published lab spectra (May 2026 file)); 5 s per run. |
| Our tool alone, second lab filetyped tool, fresh upload each run, no language model in the loop | 100 | 100 | 100 of 100 | 1 | The same result every time (a second researcher's spectra, five steps); 39 s per run. These are the runs of 18 Oct, after a fix. The first 100 runs (17 Oct) gave 98 of 100: a second request arriving between two steps made the service drop the first request's cleaning step, so the fit ran on uncleaned data. The service now saves each cleaning step as it happens. |
| Omicron with our toolthe private model we run on our own hardware | 100 | 94 | 72 of 94 | 4 | The tool returned the same exponent (1.0048) in 93 of 94 completed runs; the model's final line wrote it to four decimals in 72 runs and rounded it to fewer in 21. 6 of 100 runs stopped before the fit and gave no number. The 1 other run(s): run 91 (00:49–00:53Z on 18 Oct) returned 0.9973. It ran while we were deliberately reproducing, on the same service, the fault described above (a request's cleaning step is dropped when another file is opened between its steps). We could not replay that run's exact call sequence afterwards, so for this one run the fault is the coincident explanation, not a proven one. We count it against ourselves; that fault was fixed on 18 Oct. The fit window here was the one the tool proposes from the data (1.23–1.45 eV); our tool called directly used the window of the published method (1.28–1.40 eV), which is why the two rows of ours print different exponents — each is repeatable, and the window is the one choice that is printed. |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | 30 | 29 | 4 of 29 | 20 | 20 different exponents in 29 usable runs, from 0.73 to 1.21; one run gave no result line. |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | 30 | 30 | 7 of 30 | 20 | 20 different exponents in 30 runs at the high reasoning setting, from 0.69 to 0.93: a narrower spread than at the default, still 20 different answers in 30 runs. |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | 30 | 30 | 3 of 30 | 19 | 19 different exponents in 30 runs, all between 0.97 and 1.03; the agent wrote and ran its own fitting code each time. |
ClaudeClaude Opus 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run (vendor's top model, check row) | 10 | 10 | 7 of 10 | 4 | 4 different exponents in 10 runs, between 0.988 and 1.003 (vendor's top model, check row); the agent wrote and ran its own fitting code each time. |
Electron-microscope pattern
Measured: the period of a surface pattern in nanometres; accepted range 880–1,020 nm with the scale stated. Input: available on request (its owner has not cleared it for publishing).
| Tool | Runs | Usable | Inside the range | Different answers | What happened |
|---|---|---|---|---|---|
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | 30 | 30 | 26 of 30 | 9 | 9 different values; 26 of 30 inside the accepted range; one run answered 57 nm. |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | 30 | 30 | 28 of 30 | 11 | 11 different values; 28 of 30 inside the accepted range. |
Deadline in a civil case
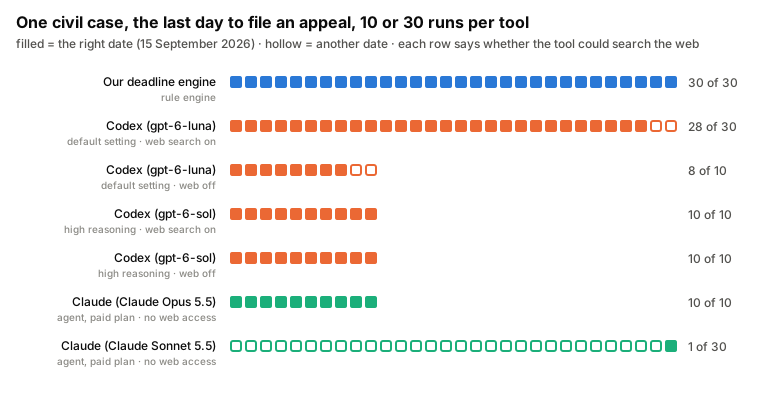
Measured: the last day to file an appeal; right answer Tuesday 15 September 2026 with the article and the August rule. Input: published with the bundle.
| Tool | Runs | Usable | Right date | Different answers | What happened |
|---|---|---|---|---|---|
| Our deadline enginea rule engine, not a language model: the period, the start rule and the August exclusion are applied from the article text | 30 | 30 | 30 of 30 | 1 | 30 of 30 the right date, the August rule printed in 30; the 30-day period comes from the article the user opens, so the engine does not restate its number. |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default, live web search on (the tool's default) | 30 | 30 | 28 of 30 | 2 | 28 of 30 right with the August rule cited, with live web search on; 2 runs ignored the August rule. |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default, web search off | 10 | 10 | 8 of 10 | 2 | 8 of 10 right with the August rule cited, from knowledge alone; 2 runs ignored the August rule. |
Codexgpt-6-solCodex CLI 0.163.0, reasoning effort high, live web search on (vendor's top model, check row) | 10 | 10 | 10 of 10 | 1 | 10 of 10 right with the August rule cited, with live web search on. |
Codexgpt-6-solCodex CLI 0.163.0, reasoning effort high, web search off (vendor's top model, check row) | 10 | 10 | 10 of 10 | 1 | 10 of 10 right with the August rule cited, from knowledge alone. |
ClaudeClaude Opus 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run (vendor's top model, check row) | 10 | 10 | 10 of 10 | 1 | 10 of 10 right with the August rule cited, from knowledge alone (no web access). |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | 30 | 30 | 1 of 30 | 4 | 1 of 30 right; 20 runs ignored the August rule, 9 misapplied the court vacation (no web access). |
02/Privacy
Privacy test, October 2026
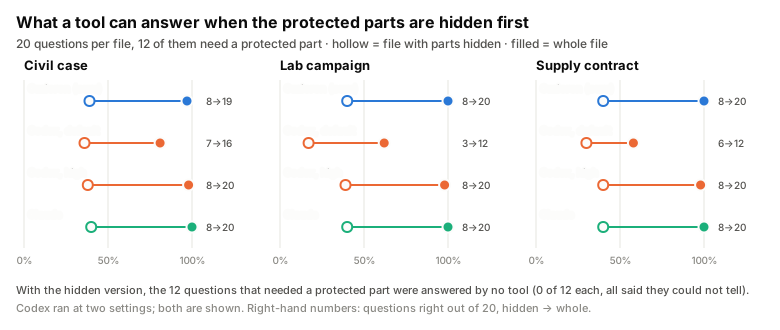
Three invented working files, 20 questions each; 12 of the 20 need a part that a rule protects (a lawyer’s duty of secrecy, the GDPR, a trade-secret clause). Each tool answered each file 5 or 10 times with those parts hidden and as many with the whole file. Runs made 17 October 2026.
We compared against the model each vendor sells most of; on the legal file we also ran each vendor's top model. One vendor model is shown twice, at its default setting and at its high reasoning setting, because the two differ.
Civil case
| Tool | File it saw | Correct | Couldn’t say | Wrong | The 12 hidden-field questions |
|---|---|---|---|---|---|
| Omicron with our toolthe private model we run on our own hardware | whole file | 19.4 of 20 ± 0.6 | 0.2 of 20 | 0.4 of 20 | 11.8 of 12 ± 0.5 |
| Omicron with our toolthe private model we run on our own hardware | protected parts hidden | 7.8 of 20 ± 1.4 | 12 of 20 | 0.2 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | whole file | 16.2 of 20 ± 1.2 | 0 of 20 | 3.8 of 20 | 8.5 of 12 ± 1.1 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | protected parts hidden | 7.2 of 20 ± 1.4 | 12 of 20 | 0.8 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | whole file | 19.6 of 20 ± 0.4 | 0 of 20 | 0.4 of 20 | 11.8 of 12 ± 0.5 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | protected parts hidden | 7.6 of 20 ± 1.4 | 12 of 20 | 0.4 of 20 | 0 of 12 ± 0.4 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | whole file | 20 of 20 ± 0.4 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.4 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-solCodex CLI 0.163.0, reasoning effort high (vendor's top model, check row) | whole file | 20 of 20 ± 0.8 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.7 |
Codexgpt-6-solCodex CLI 0.163.0, reasoning effort high (vendor's top model, check row) | protected parts hidden | 8 of 20 ± 2 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.7 |
ClaudeClaude Opus 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run (vendor's top model, check row) | whole file | 20 of 20 ± 0.8 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.7 |
ClaudeClaude Opus 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run (vendor's top model, check row) | protected parts hidden | 8 of 20 ± 2 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.7 |
Lab campaign
| Tool | File it saw | Correct | Couldn’t say | Wrong | The 12 hidden-field questions |
|---|---|---|---|---|---|
| Omicron with our toolthe private model we run on our own hardware | whole file | 20 of 20 ± 0.4 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.4 |
| Omicron with our toolthe private model we run on our own hardware | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | whole file | 12.4 of 20 ± 1.4 | 0 of 20 | 7.6 of 20 | 7.4 of 12 ± 1.1 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | protected parts hidden | 3.4 of 20 ± 1.2 | 13 of 20 | 3.6 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | whole file | 19.6 of 20 ± 0.4 | 0 of 20 | 0.4 of 20 | 11.8 of 12 ± 0.5 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | protected parts hidden | 7.8 of 20 ± 1.4 | 12 of 20 | 0.2 of 20 | 0 of 12 ± 0.4 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | whole file | 20 of 20 ± 0.6 | 0 of 20 | 0 of 20 | 11.9 of 12 ± 0.5 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
Supply contract
| Tool | File it saw | Correct | Couldn’t say | Wrong | The 12 hidden-field questions |
|---|---|---|---|---|---|
| Omicron with our toolthe private model we run on our own hardware | whole file | 20 of 20 ± 0.6 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.4 |
| Omicron with our toolthe private model we run on our own hardware | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | whole file | 11.6 of 20 ± 1.4 | 0 of 20 | 8.4 of 20 | 4.9 of 12 ± 1.1 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | protected parts hidden | 6 of 20 ± 1.4 | 12.4 of 20 | 1.6 of 20 | 0 of 12 ± 0.4 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | whole file | 19.6 of 20 ± 0.6 | 0 of 20 | 0.4 of 20 | 11.6 of 12 ± 0.6 |
Codexgpt-6-lunaCodex CLI 0.163.0, reasoning effort high | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | whole file | 20 of 20 ± 0.4 | 0 of 20 | 0 of 20 | 12 of 12 ± 0.4 |
ClaudeClaude Sonnet 5.5run as an agent with a shell on a paid plan (tier not verified), fresh agent per run | protected parts hidden | 8 of 20 ± 1.4 | 12 of 20 | 0 of 20 | 0 of 12 ± 0.4 |
Correct, couldn’t say and wrong are averages over the runs, out of 20, with the 95% margin of error. “Couldn’t say” counts apart from “wrong”: saying a fact can’t be found in what you were given is the honest answer to a hidden field.
03/Harder questions
Harder questions, October 2026
Three invented working files, 10 questions each that need two or more facts from different parts of the file and a calculation or a rule (a deadline across a public holiday, a tiered price with a discount, a lab quantity from several tables). Each tool answered each file 10 times with the whole file. Answers were checked by a script against a written answer key with worked reasoning; the key was solved independently twice before use. On the legal file the test was repeated with the protected parts hidden. Runs made 17 October 2026 – 18 October 2026.
| Tool | Civil case, harder, correct of 100 | Lab campaign, harder, correct of 100 | Supply contract, harder, correct of 100 | Civil case, parts hidden (of 100 answers) |
|---|---|---|---|---|
| Omicron with our toolthe private model we run on our own hardware | 100 | 100 | 98 | 40 open answered · 54 said it was hidden · 6 guessed · 0 wrong (in 6 of 10 runs it assumed the hidden residence on one question and answered as if it knew it; the assumed answer happened to be right) |
| Claude Sonnet 5.5agent with a shell, paid plan (tier not verified) | 100 | 100 | 98 | not run |
| Claude Opus 5.5agent with a shell, paid plan (tier not verified); vendor's top model, check row | 97 | 100 | 100 | not run |
| GPT-6 SolCodex CLI 0.163.0, reasoning high, web search off; vendor's top model, check row | 97 | 100 | 100 | 40 open answered · 60 said it was hidden · 0 guessed · 0 wrong |
| GPT-6 LunaCodex CLI 0.163.0, reasoning high, web search off | 99 | 96 | 85 | 40 open answered · 56 said it was hidden · 4 guessed · 0 wrong (4 runs guessed on one question) |
| GPT-6 LunaCodex CLI 0.163.0, vendor default (reasoning off), web search off | 46 | 37 | 39 | 28 open answered · 50 said it was hidden · 1 guessed · 9 wrong (9 confident wrong answers on hidden facts) |
With the whole file, the top models and Omicron answer almost everything; the differences are in single questions (one run forgetting the 28 October holiday, a rounding step). The vendor's default setting is far behind. With parts hidden, every model lost the questions that needed them; the honest result for us is that Omicron sometimes filled a hidden fact in from context instead of saying it was hidden.
04/What leaves
What leaves the building
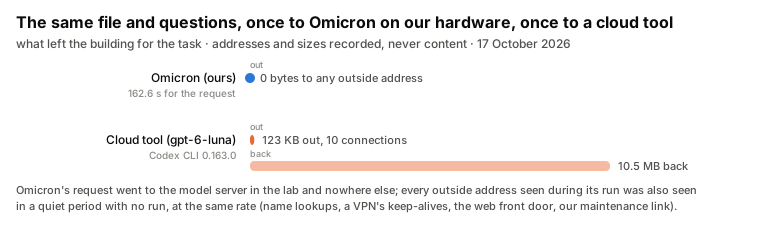
The same request (a 36.5 KB working file with 20 questions) was sent once to Omicron through our normal chat path and once to a cloud tool through its own command-line client, from the same machine. For the whole of each run we recorded where the machine sent packets (addresses and sizes only, never content) and, for the cloud run, the bytes its own program sent. 17 October 2026.
| Time for the request | Sent outside for the task | Received from outside | Outside destinations | |
|---|---|---|---|---|
| Omicron with our tool | 162.6 s | nothing | nothing | none |
Cloud tool via its command-line clientgpt-6-lunaCodex CLI 0.163.0, reasoning effort at the vendor default | 10.5 s | 123 KB | 10.5 MB | the vendor's service, reached through a content-delivery network edge; the vendor is based in the United States |
- The request went to the model server in the lab and nowhere else. Every outside address seen during the run was also seen in a quiet period with no run, at the same rate: the machine's own background (name lookups, a VPN's keep-alives, the web front door, our maintenance link).
- Ten encrypted connections to one destination. The 123 KB out is the file, the questions and the client's own overhead; the 10.5 MB in is what the client fetched back, most of it not the answer.
- The web page itself reaches users through a content-delivery network, as most websites do; what the model does with a file never goes there. A customer installation on its own network has no such hop.
- While we ran this test our maintenance tools kept their own link to their vendor; a customer installation does not have one.
- One of our own machines sits off-site and is reached over an encrypted link; it is ours, it is not the cloud, and it was not used by this test.
05/From the paper
First test, May 2026
One real lab measurement, the same file and request to each tool, four runs each, all on paid plans with every feature on.
| Tool | Runs | Usable | Same answer | What happened |
|---|---|---|---|---|
| Our tool | 4 | 4 of 4 | 4 of 4 | The same result in all four runs, 34 seconds each. |
| GPT-5.5 | 4 | 4 of 4 | 0 of 4 | Saw one peak in some runs and two in others. Its results moved by up to 54.8% from run to run. |
| Claude Sonnet 4.6 | 4 | 4 of 4 | 0 of 4 | Measured the wrong feature in most runs, and drew its boundaries differently each time. |
| Gemini 3.1 Pro | 4 | 0 of 4 | 0 of 4 | Got a unit conversion wrong every time, so none of its results were usable. |
Runs made before publication, May 2026. Source: Adamidis et al., 2026
06/Limits
What this does not prove.
- These tests measure consistency on a few tasks and what each tool can answer with the data it may see. They do not show that our system is more accurate in general.
- The privacy files are invented. Real files are longer and messier.
- Each outside tool was used as sold, with no special instructions. A skilled user could get better answers from any of them.
- Model names and plans change often. The dates above are the only ones these results speak for.
- Settings matter: the same vendor model gave very different privacy-test results at its default and at its high reasoning setting. Both rows are shown, with the setting printed.
Download every request, raw answer and grader (830 KB, SHA-256 abf1ada8c652cba6f0ca25e529ac25541960ecefc2ed3449a2f197856fe00e70). The lab files are not in it until their owners agree.
Test protocol v1.1 + SEM/LAW addendum, SHA-256 1831770b67f553537927f256f92ba5f787fc3f3b1112464497f35b9a46fee13d